SC26 Round-Up: PCIe Gen6 Flash Ships, VAST Adds Per-Job Storage QoS, TOP500 Barely Moves
- Brian Beeler
- 957 views
Supermicro says its PCIe Gen6 all-flash server is shipping, VAST ties storage QoS to Slurm and PBS Pro jobs, and the TOP500 has its quietest turnover yet.
The headline launches at SC26 in Chicago get most of the attention, but the second tier of announcements is where the practical changes for storage and server teams sit. Three threads stand out to me. PCIe Gen6 storage servers are moving from roadmap slides into shipping product. Storage is starting to understand which job is asking for I/O. And KV cache has become a storage tier in its own right. The TOP500 result is almost a non-event by comparison, though the numbers behind it are worth a look.
TOP500: The Quietest Turnover on Record
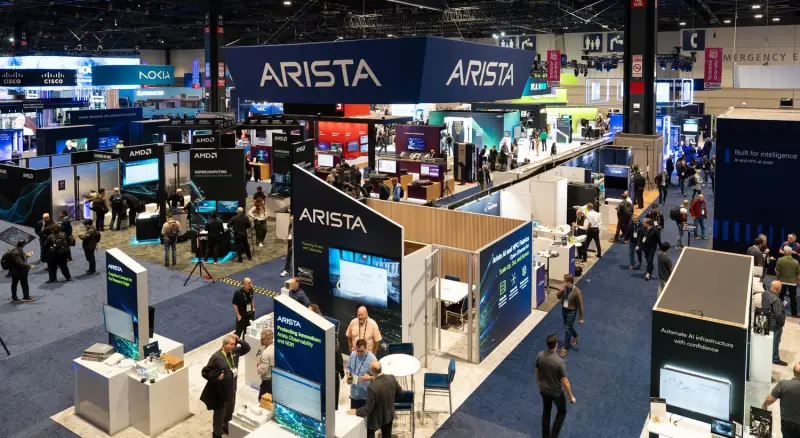
The 68th TOP500 list left the top 10 unchanged from the June list. China's LineShine at the National Supercomputer Center in Shenzhen holds No. 1 at 2.198 exaflops on HPL, ahead of El Capitan at 1.809, Frontier at 1.353, Aurora at 1.012 and JUPITER Booster at 1.000. Only 27 systems are new, which is 5.4 percent of the list and, according to the list's organizers, the lowest turnover in its history. Combined performance rose 4.4 percent to 19.57 exaflops, the entry point at No. 500 moved up to 2.857 petaflops, and 291 systems now use accelerators.
The highest-ranked newcomer is HANGANG at KISTI in South Korea, an HPE Cray EX254n built on NVIDIA GH200 Superchips that debuts at No. 12 with 342.6 petaflops. HPE's Lux system at Oak Ridge enters two places lower at No. 14. LineShine also leads the HPCG benchmark at 22.00 petaflops, and El Capitan leads the mixed-precision HPL-MxP test at 16.7 exaflops. The Green500 top 10 is unchanged too, with France's KAIROS first at 73.28 gigaflops per watt on a BullSequana XH3000 with GH200 Superchips.
Why does a stable list matter to a storage or infrastructure team? Because the slow churn at the top means the big procurement cycles are working through slowly, and the interesting movement is happening lower in the list and in the I/O benchmarks. That's where the storage story is.
IO500: Aurora Takes the Production List by a Wide Margin
Argonne's Aurora leads the SC26 IO500 production list with a new DAOS submission scoring 46,192.01 from 4,096 client nodes. The run delivered 12,296 GiB/s of bandwidth and 173.5 million metadata operations per second. That score is about 13 times that of LRZ's SuperMUC-NG Phase 2 in second place, which posted 3,470.22. KISTI's HANGANG, the TOP500 newcomer, enters third on Lustre at 1,155.89. Eight of the 52 production entries are new, including IBM's Blue Vela on Storage Scale System 6000, Georgia Tech's Nexus on VAST, and two DDN EXAScaler systems at Purdue.
The research list has no new entries in its top five, and Pengcheng Cloudbrain-II still leads it at 210,255. Much of the new activity in the 10-node category comes from vendor labs. Hammerspace entered a Tier 0 configuration over pNFS at No. 29 with a score of 688.01 and 449.86 GiB/s of bandwidth. Dell's Lightning File System scored 568.66 at No. 37, and DDN's AI400X3M with EXAScaler scored 317.47 at No. 53. IBM added several Storage Scale System 6000 results, and the Telecommunications Technology Association in Korea placed a 10-node DAOS system from Gluesys at No. 19 with 1,242.79.
My read: the 10-node results are the ones worth reading closely if you're sizing a mid-scale file tier. Scores at that size tell you more about what a modest configuration can do than the Aurora number does, even though the Aurora number is the one that will get quoted.
PCIe Gen6 Arrives in Shipping Storage Servers
Supermicro says its first PCIe Gen6 all-flash storage servers are shipping, starting with a Petascale system built on AMD EPYC 9006 SP7 processors. The 2U chassis takes up to 32 E3.S NVMe SSDs, which Supermicro puts at 3.93PB using 122.88TB drives. It has room for up to four x16 network cards. Supermicro claims up to 100 percent more sequential read bandwidth than PCIe Gen5, though it did not describe the test configuration behind that figure. More models are due as AMD releases SP8 versions of the processor.
Supermicro lists Hammerspace, IBM, MinIO, Nutanix, Scality, VAST Data, VDURA and WEKA as software-defined storage vendors validated on the platform. The platform spans its CloudDC, GrandTwin and Hyper families. IBM said Storage Scale runs on the new server for inference pipelines that include KV cache, a pairing the two companies introduced on earlier Supermicro hardware.
Two other vendors are showing PCIe Gen6 storage designs on the same processor family, which makes this a more interesting moment than a single product launch. AIC and MSI are both showing E3.S configurations, and Supermicro is the only one of the three that says its system is shipping. If you're planning a Gen6 refresh, expect the storage software validation lists to decide which platforms you can actually buy in the next budget cycle, not the spec sheets.
AIC and MSI: Flash Shelves, JBODs and EPYC 9006 Servers
AIC is organizing its SC26 display around the storage tiers of an inference cluster. Its premise is that KV cache is moving to shared flash close to the GPUs, with capacity storage behind it. The F2026 is a 2U PCIe Gen5 JBOF with 26 dual-port NVMe bays, dual canisters and support for up to four DPUs, serving flash over NVMe-over-Fabrics. MangoBoost builds its Mango KESAR-E enclosure on this chassis. The HA2026-HC puts two active-active AMD EPYC nodes in front of the same 26 bays. The newest AIC system, the SB103-JP, is a 1U server with up to 16 E3.S PCIe Gen6 NVMe bays and a single EPYC 9006 processor.
For capacity, AIC offers the SB407-ID, a 4U server with 60 hot-swap 3.5-inch bays, six rear PCIe Gen5 NVMe bays and dual Intel Xeon 6 processors. The J4078-02-04X is a 4U 78-bay 24Gb/s SAS JBOD. On the compute side, the 5U CB502-NM takes dual EPYC 9004 or 9005 processors and up to eight dual-slot GPUs at up to 600W each. AIC did not give availability or pricing for any of these systems.
MSI's EPYC 9006 servers are the part of its lineup that hadn't been shown before. The 2U dual-socket CX272-S6082 has 32 DDR5-8000 RDIMM slots and 32 front E3.S 1T bays on PCIe 6.0 x4. The 1U single-socket CX172-S4081 has 16 of each. For multi-node work, the ORv3 CD182-S6091-X2 packs two direct liquid-cooled, dual-socket nodes into 1OU, with 32 DDR5-8000 slots and four E1.S PCIe 6.0 bays per node. The air-cooled CD281-S4091-X2 puts two single-socket nodes in 2OU, each with eight E3.S 1T bays. MSI lists CPU TDPs of up to 600W on its Open Compute platforms. Its Xeon 6 versions stay on PCIe 5.0 U.2 bays, and MSI also lists Instinct MI350P configurations without model details or dates.
Phison: Gen6 Controllers, Computational Drives and Mixed Media
Phison previewed three storage technologies at SC26. Its X3 (PS5303) enterprise SSD controller targets up to 28GB/s of sequential throughput and 6.8 million IOPS over PCIe Gen6 x4 with NVMe 2.3. That's close to twice what Gen5 drives deliver. The company says its PS7161 is the first PCIe 6.0 redriver on the PCI-SIG Integrators List.
The computational storage design puts an NPU rated at 36,800 DMIPS and 64GB of memory inside the drive. Phison lists support for PyTorch, vLLM, OpenVINO and llama.cpp, and estimates it can cut data transfers by 10 to 100 times for workloads that suit it. The third design, Mixed Media, places high-endurance pSLC and high-capacity QLC flash behind one 16-channel controller. In that design a system needs no dedicated cache drives, and every bay adds usable capacity. Phison notes that losing one of 24 such drives removes about 4 percent of the cache, where a design with dedicated cache drives would lose 25 percent. Phison gave no product names, capacities or dates for the computational or mixed-media drives.
Phison also launched the Phison AI Data Platform with generative BI, an on-premises system sold in four-GPU or eight-GPU configurations and available now. It pairs the company's aiDAPTIV cache memory with Wren AI, which turns natural-language questions into SQL-backed dashboards, and uses TrueNAS as a storage target for backup and restore. In Phison's lab testing with the Wren AI agent, aiDAPTIV supported twice the concurrent sessions on the same GPUs, with 3.7 times faster time to first token. Those are Phison's numbers from its own test conditions, so treat them as a starting point for your own benchmarking.
KV Cache Moves Onto Flash: TRUSTA and Hitachi Vantara
TRUSTA, the enterprise storage brand of ADATA, is exhibiting at SC for the first time with an upgraded AI Scaler Toolkit. The software integrates vLLM and spreads KV cache across three tiers: GPU memory for active requests, DRAM as a fast cache, and TRUSTA PCIe Gen5 SSDs as a large tier that persists across restarts. Long contexts reload from flash, and conversations resume after a reboot without being recomputed. TRUSTA published no time-to-first-token or throughput figures for the offload, which is a gap next to Lightbits Inferra, which launched with session-density claims.
The toolkit supports llama.cpp and the Strata inference engine. TRUSTA's Strata build uses Intel AMX to speed prompt prefill by up to 25 percent over upstream Strata v0.2.11. That figure comes from TRUSTA's testing on a Xeon w5-3535X with one RTX 6000 Ada GPU. The gain was about 11 percent on a single 8K-token input and about 25 percent in multi-turn conversations, and TRUSTA found no gain for inputs above 12K tokens. The drives involved are the TD7P51 ECO and T7P5, PCIe Gen5 SSDs up to 15.36TB in U.2, E1.S and E3.S, rated at up to 3 DWPD, with Flexible Data Placement and power draw under 20W.
Hitachi Vantara took a different angle. It lowered the entry point for VSP One Object to a four-node starting configuration with a simplified deployment process. It says continued small-object tuning delivers up to 5.5 times faster data access for AI, analytics and S3 workloads. The object store can now run analytical queries directly against Iceberg, Parquet, JSON and CSV data, which Hitachi Vantara puts at up to 5 times faster with 80 percent fewer CPUs. The company gave no baseline or test configuration for any of the three figures, but it did expand multisite replication and regional capabilities. On the software side, Hitachi iQ Studio adds filesystem and NFS knowledge sources for retrieval-augmented generation, a Model Gateway for governed access to local and external models, Model Context Protocol connectivity and ServiceNow support. Hitachi Vantara listed no node specifications, capacities, pricing or availability dates.
VAST Data Puts Job Identity Into the Storage Layer
The VAST item I'd put at the top of a storage team's reading list is Job-Level Quality of Service for the VAST AI Operating System. It carries a job's identity from the workload manager into the storage layer, which has been a gap on shared clusters for a long time. The VAST NFS client tags I/O requests with configurable job identifiers from Slurm, PBS Pro or LSF. Administrators can set separate bandwidth and IOPS policies per job, including for several jobs running on one node. Policies can be changed while jobs run, with no restart, application change or remount required. An optional open-source VNFS Collector reports per-job bandwidth, IOPS and errors to Prometheus, Grafana or the VAST DataBase.
The feature targets the problem of one I/O-heavy job starving the others on the same file system. VAST's pitch is that limits can be applied without interrupting the job causing the contention. Teams in this position often end up with informal rules, such as scheduling heavy checkpoint jobs at night or asking users to throttle themselves, and per-job policies replace that with something you can enforce and measure. VAST plans general availability with VAST AI OS 5.6 by February 2027, and the feature requires VAST NFS 4.8 or later. The company is demonstrating it at SC26, says the design also supports Kubernetes and other orchestrators, and has published no performance figures. Before you plan around it, check whether your scheduler and client versions match those requirements.
Cloud and Fabric: Managed Lustre, Vera Rubin and Photonic Memory
Google Cloud's SC26 summary puts Managed Lustre at up to 10TB/s of read throughput. It cites GPUDirect Storage over RDMA and an 80PB Dynamic Tier that mirrors to Cloud Storage. Managed Lustre is one of the cloud routes to EXAScaler that DDN cited in its software-defined EXAScaler 7 announcement. Google gave no configuration behind the throughput figure. On the compute side, A5X bare metal instances on NVIDIA Vera Rubin NVL72 are newly available alongside the A4 and A4X Blackwell instances, and Google's Batch service now supports single-host TPU slices.
Marvell announced no new products at SC26. It is using the show for demonstrations built on one argument: AI clusters are now held back by memory and connectivity as much as by compute. The demos include a Photonic Fabric memory module, Structera CXL add-in cards for memory expansion and compression, Alaska A active electrical cables at 800G and 1.6T, and Teralynx 10 and T100 switch silicon. OCTEON DPU storage designs and Bravera SSD controllers appear alongside. Marvell gave no performance, reach or power figures and did not name the partners involved.
The Server Vendors: Vera Rubin, HGX Rubin NVL8 and Liquid Cooling
Compal is showing three NVIDIA-based servers: the air-cooled SGX30-2 and the direct liquid-cooled OG430-2-L1, both built on HGX B300, and the OG231-2-L1 on HGX Rubin NVL8. It also displays an NVIDIA Vera CPU compute tray alongside BlueField-4 DPUs, ConnectX-9 SuperNICs and Spectrum-6 Ethernet switches. Compal published no specifications, availability or pricing. It pointed to its Daxi AI server manufacturing center in Taiwan, which opened in August 2026, and to added capacity in Texas and Vietnam.
ASUS says it is ramping volume shipments of NVIDIA Vera Rubin NVL72 racks in the fourth quarter. Its AI POD XA VR721-E3 holds 72 Rubin GPUs and 36 Vera CPUs in a fully liquid-cooled rack. ASUS is showing it with NVIDIA Groq 3 LPX and Vera CPU trays, a Spectrum-X SN6600 switch and NVIDIA CMX context memory. Two HGX Rubin NVL8 systems are on display: the 3U hybrid-cooled XR R1I12B-M1BHFS and the 2U liquid-cooled XR R1I12B-M1BLFS. ASUS gave no shipment volumes or customer names. On storage, it is showing the VS320D-RS26N enterprise storage platform, the OJ340A-RS60 object storage system and the RS500A-E14B-R12U, a 1U EPYC 9006 server with PCIe 6.0 and NVMe storage. It describes automated L10 and L11 manufacturing and a six-layer validation process that runs from node-level checks to full-rack testing. It also uses NVIDIA's Omniverse DSX Blueprint with Schneider Electric, AVEVA and IBM to simulate facilities before deployment. A second release adds the RS700A-E14B-R16U, a dual-socket 1U EPYC 9006 server with PCIe 6.0 and up to 16 E3.S drives.
Giga Computing's new 6U liquid-cooled blade chassis puts cold plates on the CPUs, memory and NICs. The company says that captures nearly 90 percent of system heat. The B685-D80-LS1 takes AMD EPYC 9006 processors for up to 5,120 cores in one chassis, and the G684-A80-LAS1 uses Xeon 6 in the same form factor. The H295-D80-CS1 is a 2U four-node server with closed-loop liquid cooling, built for data centers without facility water. On the GPU side, the G3L4-SD5-LA08 is GIGABYTE's first server for HGX Rubin NVL8. It is a 3U design that adds U.2 drives for KV caching. The G494-AB0 is a prototype for Intel's Diamond Rapids Xeon with 16-channel memory and PCIe Gen6 GPUs. Giga Computing's GIGAPOD management rack is shown with VAST and WEKA storage and UfiSpace switches, with no availability dates.
MiTAC and Skymizer are proposing an on-premises inference design that runs prefill on GPUs and decode on Skymizer's HTX301 accelerator cards. Prefill runs on the 8U G8825Z5, with AMD EPYC 9575F or 9755 processors and Instinct MI350X GPUs. It passes the KV cache over the network to the 4U air-cooled G4520G6, a Xeon 6 server with eight HTX301-4S cards at 256GB each, for 2TB of accelerator memory. MiTAC says the decode server is designed to run models as large as the 2.8-trillion-parameter Kimi K3, and it published no throughput or latency results. A 52U liquid-cooled rack on the show floor holds 12 G4826Z5 servers with 96 Instinct MI355X GPUs. MiTAC puts that at 50 percent higher GPU density than conventional deployments, without defining the baseline. A proof of concept with ZutaCore applies waterless two-phase direct liquid cooling to the same server, rated for more than 4,000W of thermal design power and an annualized partial PUE of 1.03. A storage rack runs DDN Infinia on seven GC68C-B8056 1U servers.
Pegatron's NVIDIA Vera CPU Rack follows the MGX reference design with 256 liquid-cooled Vera CPUs, more than 22,500 cores and up to 300TB/s of aggregate LPDDR5X memory bandwidth. Its Vera Rubin NVL72 rack is the RA4803-72N3. The 2U AS210-2T1-8H3 is a liquid-cooled HGX Rubin NVL8 system with a choice of Xeon 6 or EPYC 9006 host processors. For EPYC 9006, Pegatron is introducing the MS310-2A2E, a 2OU two-node server fed from a 48V busbar, alongside the GS203-2A2 and GS205-2A2E dual-socket servers. The SS201-1A1 storage platform takes up to 32 E3.S NVMe bays.
What to Check Before the Next Change Window
If you run shared HPC or AI storage, the actionable items from SC26 are the job-aware QoS feature and the PCIe Gen6 storage servers. Confirm your scheduler versions and NFS client levels against VAST's stated requirements, and find out whether your storage vendor's Gen6 platform appears on the validation list for the software you run. For KV cache, the vendor numbers mostly come from their own test setups, so run your own models and context lengths before you size flash tiers. Most of the rest, including the Vera Rubin racks and liquid-cooled blades, has no pricing or availability dates yet. Plan for those as roadmap items until the vendors confirm them.