Hammerspace Sells Its Data System With Open Flash Tray Rated at 390GB/s
- Brian Beeler
- 658 views
Hammerspace now sells its software as a complete system, anchored by a 1U DPU flash tray rated to 9.83PB raw. Quotes are open, and shipments begin in the first half of 2027.
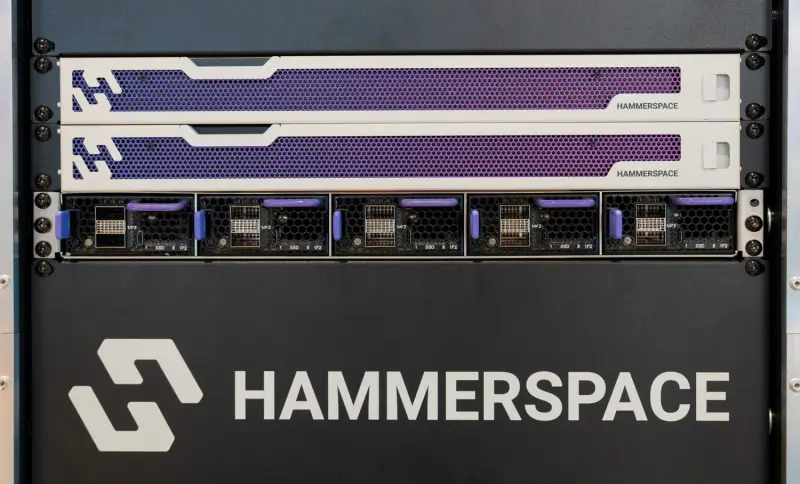
Hammerspace is no longer only selling software. For the first time, it will sell its Data Platform as a complete system, rebranded as the Hammerspace Data System, with the company supplying the software, metadata nodes and storage hardware. The hardware centrepiece is the Hammerspace Open Flash Platform (OFP), a 1U tray holding up to five DPU-based flash nodes with no x86 storage server. Hammerspace rates a full tray at 390GB/s of writes and 15 million IOPS per rack unit, with up to 9.83PB raw. OFP is open for quotes now and ships in the first half of 2027.
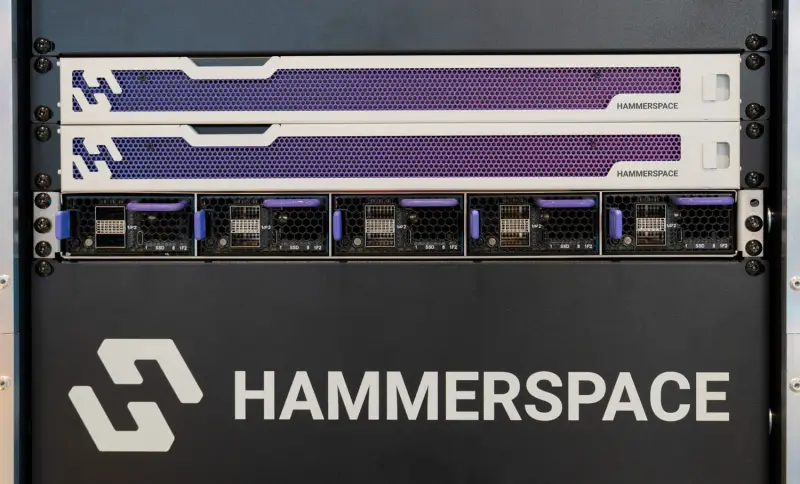
What the Data System Actually Is
At its core, Hammerspace sells a parallel global file system. It separates metadata from the data path and presents existing NAS, object and cloud storage as a single namespace, reachable over pNFS, NFS, SMB and S3. Linux clients connect through the NFSv4.2 client that ships with standard distributions, so there's no proprietary agent to install. Hammerspace says it engineered the Flex Files layout it uses for the NFS specification.
The Data System builds on that software and is organised around five capabilities: data unification, intelligence, orchestration, acceleration and storage. Intelligence and storage are the new pieces. The commercial change matters as much as the technical one. Customers can now buy the whole stack from Hammerspace, and the metadata nodes, which Hammerspace calls Anvils, are 1U x86 servers in Standard and Large M-Series configurations. Each site gets a high-availability pair of Anvils, each with two 100GbE data ports, to run the control plane that manages the namespace and executes placement policies.
Software-only deployment on customer hardware continues. So do Hammerspace Ready Nodes from Dell, Supermicro and Hitachi Vantara, along with marketplace images on AWS, Azure, Google Cloud and Oracle Cloud. The software is licensed by subscription, priced on capacity under management.
This option addresses a pattern Hammerspace says it keeps seeing. The software wins the technical evaluation, then the customer buys an integrated product from another vendor because the purchase is simpler. Here's the thing: a bundled system solves that procurement problem without changing what the software does. Evaluations usually still start as a proof of concept, with bring-your-own-licence cloud images as the self-service route.
Hammerspace storage typically enters when a new GPU cluster needs high-performance storage while existing data sits on NetApp, PowerScale or object systems. The namespace can take those systems over in place. A block array joins only if it can be mounted over NFS.
Clusters join into one global file system, and metadata replicates between sites continuously, with about a second of lag across long distances. Data moves only when a policy or an access request calls for it, and job schedulers can trigger movement through the API and native connectors. Hammerspace's example is a life sciences customer that ingests instrument data over SMB, processes it over pNFS and serves it over S3 from the same system.
David Flynn, Founder and CEO of Hammerspace, framed the launch with a line that's worth repeating: "Simply adding more storage isn't the answer." He positioned the Data System as doing for data what AI factory designs did for compute, which is to consolidate it.
Inside the Open Flash Platform
Each OFP sled is a complete storage node, one-fifth of a rack unit wide. It carries eight U.2 or U.3 NVMe SSDs in two removable four-drive packs, two 400GbE QSFP-DD ports and a 64-core Arm DPU where an x86 motherboard would normally sit. That DPU is the Xsight Labs E1, which Xsight builds on TSMC's 5nm process with 64 Arm Neoverse N2 cores, two 400G MACs, PCIe Gen5 and a typical power figure of 70W. It runs standard Linux, and the Hammerspace file system sees each sled as an NFS server.
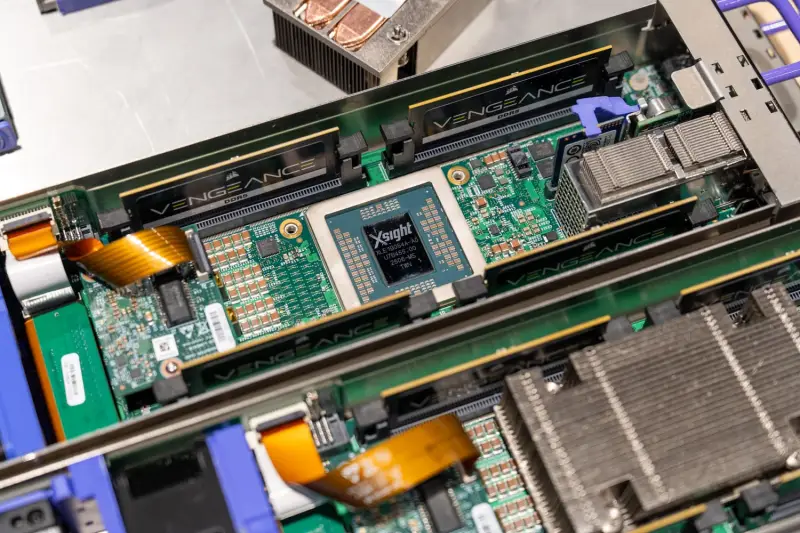
A tray takes one to five sleds. Fully populated, that's up to 40 drives, 320 Arm cores and ten 400GbE ports per rack unit. Hammerspace lists a maximum of 360W per sled and 1,800W per tray, fed by dual 2,160W Titanium power supplies. Sleds and drive packs are tool-less to service, and management runs over IPMI and Redfish.
The tray is 106.64cm deep and needs a 1,200mm rack, so shallower enterprise cabinets are out. Hammerspace puts its drive density at 3.3 times that of a typical 2U, 24-bay NVMe server, or 160 SSDs in 4U against 48. Cooling is air-based, with a 40C maximum inlet temperature at sea level.
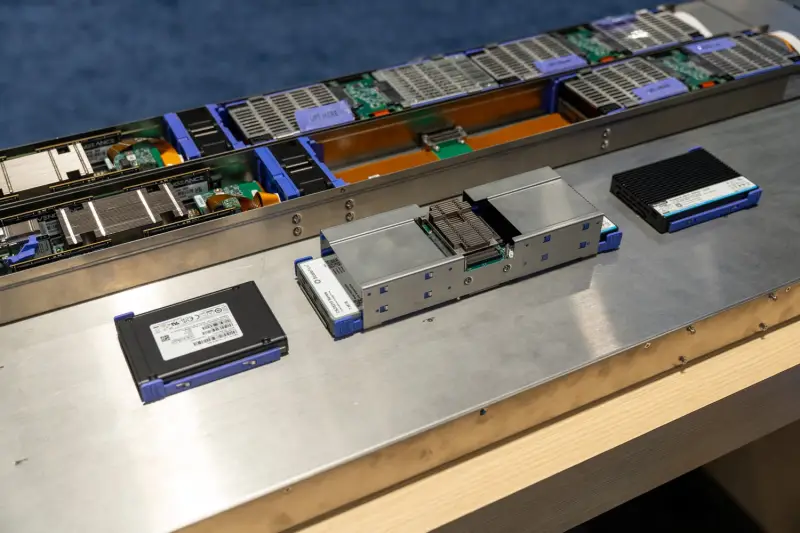
Hammerspace's maximum-capacity figures assume eight 245.76TB QLC SSDs, the largest drives it lists, with capacity in line with drives such as the KIOXIA LC9. On that basis a sled holds 1.97PB raw and a full tray holds 9.83PB. At the tray's 1,800W maximum, that works out to roughly 183W per raw petabyte. Sleds accept TLC or QLC drives on PCIe Gen5 or earlier, and Hammerspace positions TLC for performance and QLC for capacity. A 42U rack of trays would hold about 413PB and draw up to 75.6kW.
The design grows out of the Open Flash Platform initiative Hammerspace started in 2025, with Xsight Labs and Los Alamos National Laboratory among the named participants. In October 2025, Hammerspace said production systems would arrive in early 2026. The shipping window has moved by roughly a year. The sled uses U.2 and U.3 drives because those ship in volume today, even though the design has denser form factors in mind. Hammerspace and Xsight have also described a path to an exabyte per rack, more than twice what a full 42U of today's largest drives would hold.
Prototype work on the sled began about two years ago, according to Hammerspace. Early adoption has come from hyperscalers that place one or two trays at the top of each GPU rack. They're prioritising rack and performance density over power savings. In that layout, Hammerspace maps the NVMe inside GPU servers to the tier NVIDIA labels G3, and a TLC-filled OFP tray in each rack to G4.
Reading the Performance Claims
Hammerspace rates a five-sled tray at 390GB/s of write throughput without mirroring, and 15 million 4K random read IOPS. The stated test conditions are NFSv4.2 with pNFS over TCP, on a 400GbE fabric, using enterprise Gen5 TLC SSDs. Reads are rated at up to 80GB/s per sled, or 400GB/s per tray. That's about 40GB/s through each sled's two 400GbE ports. Once protocol overhead is counted, those links are nearly saturated, so the network ports set the read ceiling rather than the flash.
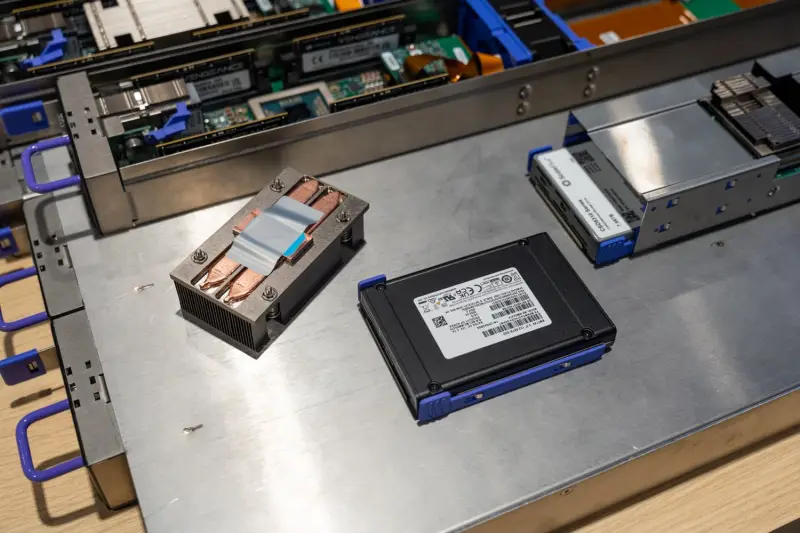
Protection is handled by mirroring, which is set per file or directory by policy and can be changed online. With two-way mirroring, writes fall to 195GB/s per tray. Three-way drops them to 130GB/s. Two-way mirroring also halves usable capacity, to about 4.9PB on a fully populated QLC tray. For data that can be regenerated, such as KV cache, Hammerspace suggests running without mirrors.
Hammerspace claims two to five times the per-rack-unit performance of an unnamed closest competitor. It hasn't published latency, client counts, or IO500 and MLPerf Storage results for OFP. We haven't run or verified these figures ourselves, so treat them as vendor numbers until independent tests appear.
| Specification | Hammerspace Open Flash Platform |
|---|---|
| Architecture | DPU-based flash storage nodes with no x86 storage server |
| Sled | 8 x U.2/U.3 NVMe SSDs in two 4-drive packs 64-core Arm DPU (Xsight Labs E1) 2 x 400GbE QSFP-DD |
| 1U Tray | 1 to 5 sleds Up to 40 SSDs Up to 320 Arm cores Up to 10 x 400GbE |
| Maximum Raw Capacity | 1.97PB per sled 9.83PB per tray Based on 245.76TB QLC SSDs |
| Read Throughput | 80GB/s per sled 400GB/s per tray |
| Write Throughput, No Mirror | 78GB/s per sled 390GB/s per tray |
| Write Throughput, 2-Way Mirror | 39GB/s per sled 195GB/s per tray |
| Write Throughput, 3-Way Mirror | 26GB/s per sled 130GB/s per tray |
| 4K Random Read | 3 million IOPS per sled 15 million IOPS per tray |
| Maximum Power | 360W per sled 1,800W per tray |
| Form Factor | 1U tray, 106.64cm deep Requires a 1,200mm rack |
| Availability | Quoting now Shipping in the first half of 2027 |
Tier 0, Tier 1 and the KV Cache Role
Hammerspace places OFP at Tier 1, behind a Tier 0 made of the NVMe already inside GPU servers. That Tier 0 is exported over NFS and pooled into a shared, cluster-wide tier, with no client or agent needed on compute nodes. Data written there is mirrored across the cluster for protection and moved to other tiers by policy. A common pattern, according to Hammerspace, is to write training checkpoints locally and let the system push older ones to object storage. The company quotes 4.4 times the sequential bandwidth and 56 percent lower latency for Tier 0 compared with external shared storage, but it hasn't published the test setup.
The KV cache role uses the same tiers. The logic is that an inference server able to reload a conversation's computed context from shared storage doesn't have to recompute those tokens on the GPU. Hammerspace doesn't manage the cache itself. It presents the pooled Tier 0 NVMe, with OFP behind it, as POSIX storage for the inference software's own cache manager.
Data Intelligence: Catalog, DeepScan and Policy
The intelligence layer starts with a catalog that indexes file and object metadata across every storage system in the namespace, without moving any data. A second layer, DeepScan, opens files to look for personal, financial and protected health information, either on demand or on a schedule. Its findings become searchable tags. Queries can be written in natural language through an LLM the customer chooses.
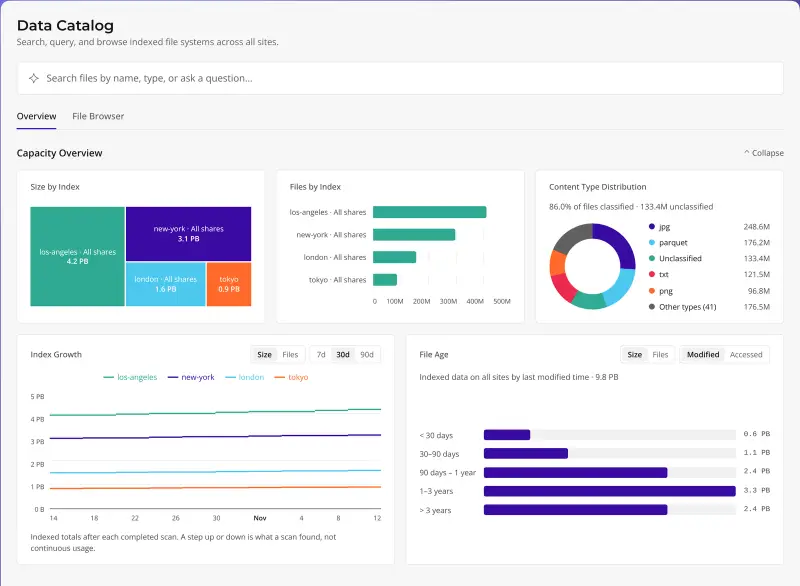
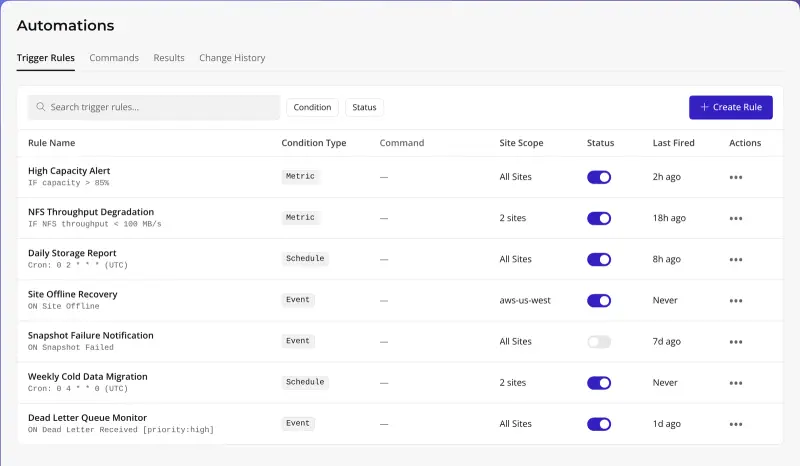
Results feed the existing policy engine, which Hammerspace calls objectives. An administrator could find every file tagged as training-ready, or every file restricted to one country, and attach a placement rule to that set. Objectives are declarative rules attached to a share, volume, directory or file. Examples include moving data untouched for 30 days or keeping three copies across three sites. New automations can trigger them from capacity thresholds, schedules and events, with a preview step before changes are approved. Tags inherit down the directory tree and follow files between storage systems and clouds. The software covers file and object stores from any vendor, but it doesn't manage structured data.
Early Customers and What to Watch
The launch reference customer is kaiko, a clinical AI company with offices in Amsterdam and Zurich that trains models on imaging and pathology data. Kaiko runs Hammerspace across Microsoft Azure and the Nebul and Nebius GPU clouds as one namespace. It uses the NVMe in its GPU nodes as Tier 0 for training, and checkpoints land on Azure Blob Storage by policy. Hammerspace says all of kaiko's ML engineering workflows on those three clusters now run on the system. That case study doesn't involve OFP hardware.
Hammerspace also told us kaiko adopted the system while growing from about 128 GPUs to more than 1,000 on Nebius. Its existing all-flash NAS in the Nebul cloud was brought into the namespace in place. Hammerspace described a second case too: an unnamed hyperscale AI research lab that replaced Amazon FSx for Lustre with a 30PB Hammerspace cluster in AWS. Lustre had been its largest source of support tickets over the previous year, and the lab is now extending the namespace to an on-premises data centre. Hammerspace cites about three times faster large-file operations there.
OFP joins a growing set of designs that put a DPU where the storage server's processor used to be. The closest is the BlueField-4 STX reference architecture NVIDIA introduced at GTC. Hammerspace's version differs because it pairs the hardware with a file system that also runs without it. Hammerspace is demonstrating the hardware at SC26 and hasn't published pricing.
My read: the bundling matters more than the tray. Teams that already run Hammerspace software can now ask for a supported hardware path, and the density numbers will carry weight for GPU operators who lack floor space. Before a 2027 purchase, though, get the latency data, the test configurations behind the 390GB/s figure, and independent benchmark results, and check that your racks are deep enough for a 1,200mm tray.


