Monitoring the Website-to-Demo Path Beyond the Homepage Check
- [email protected] (Route XP)
- 381 views
A healthy homepage doesn't prove prospects can book a demo. Here's how to monitor the full path from page load to CRM entry and split ownership across teams.

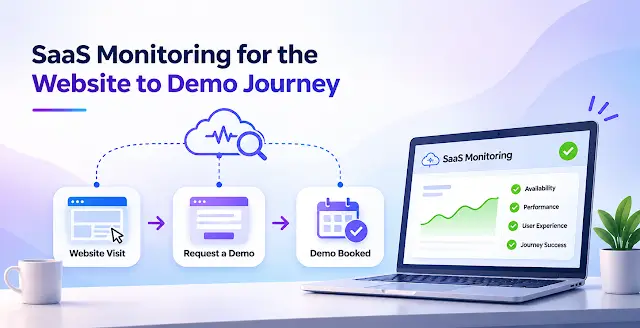
A green homepage check tells you very little about pipeline. The page can return a clean response while the demo form won't render, the scheduling widget hangs, or the submission never reaches the CRM. For a SaaS business, that gap is where leads quietly disappear. My read is that monitoring should follow the prospect's actual task: load the page, submit a demo request, and confirm the request lands in the sales system.
Start with the dependencies a visitor actually uses
The page is the visible part of a chain. DNS resolution, TLS negotiation, content delivery, application responses and third-party scripts can each fail on their own. A form might depend on a scheduling vendor's script, a chat tool or a tag manager, and any one of those can break while your servers stay healthy.
Run checks from more than one region. A route that works fine from your office can fail for users on a different network or in another country. Record the test location, the network context, the timestamp and the affected hostname with every result. Those details are often what separates a regional routing problem from a defect in your application.
Treat HTTP 200 as the start of the investigation, not the end. A page can load successfully and still hide the one element a prospect needs. That's why a browser-based check that performs the real action, filling in the form and submitting it, earns its place in the monitoring setup.
Match each signal to the layer it can prove
Dashboards full of unrelated readings generate work without answers. Before adding a metric, the team should know which layer it can confirm and what someone does next when it goes red. The table below maps common signals to the layer they point at and the first place to look.
Layer |
Example signal |
What to investigate |
DNS |
Resolution failure |
Resolver and authoritative records |
TLS |
Handshake or certificate error |
Certificate chain and configuration |
HTTP |
Error status or timeout |
Edge, origin and upstream services |
Browser |
Form missing or script exception |
Deployment and dependencies |
Integration |
Accepted request absent from CRM |
Queue, webhook and connector |
Analytics |
Expected event absent |
Consent, tags and event configuration |
Where the architecture allows, pass a correlation identifier through the submission path. It can tie a browser request to the application log, the queue message and the CRM response, so you can follow one test submission end to end. Keep personal information out of that identifier and out of diagnostic output.
Synthetic submissions need guardrails. A test demo request shouldn't become a real sales lead, trigger a customer email or inflate acquisition reports. Agree on a dedicated test destination and a cleanup process before the first run, not after the CRM fills with junk records.
Document the expected response for every check. Without a baseline, an alert tells you something changed but not whether a prospect can still finish the journey. That ambiguity slows down the person on call more than almost anything else.
Split ownership by failure point, not by dashboard
The team that sees the symptom first is rarely the team that can fix it. A drop in recorded leads might come from the page, the integration, the measurement layer or simply softer demand. Assigning ownership by failure point keeps the investigation from bouncing between departments.
In practice, engineering owns infrastructure diagnosis and application recovery. Marketing operations typically owns source tagging and lead routing rules. Sales operations confirms whether accepted requests reached the right workflow and owner. A named incident coordinator keeps those checks connected, which matters most when a campaign is driving paid traffic into a broken form.
If you bring in an external marketing agency, ask how it coordinates incident evidence with your engineers. Useful responsibilities include spotting campaign anomalies, preserving the affected page and campaign details, and deciding whether paid traffic should pause. Writing those boundaries and escalation duties into the working agreement saves arguments during an outage.
Separate tracking failures from transaction failures
Verify the business action on its own terms, apart from its analytics event. A tracking event can be missing even when the server accepted the request. The reverse also happens: an event can fire before the submission actually succeeds, which inflates conversion figures.
Google's DebugView guide explains how to inspect events during troubleshooting. Use it to confirm what the browser is sending, but don't treat it as proof that the whole submission completed. Pair it with the server record and the CRM entry.
Check what triggers each event. A button click measures an attempted action. A confirmed successful submission measures a later point in the journey. Those two numbers can diverge sharply during a fault, and mixing them up will send your team chasing the wrong problem.
Run incidents in a fixed order
A repeatable sequence protects evidence and keeps people from changing five things at once. Start from the user-visible symptom and work down the dependencies that support it.
- Confirm the failure with a controlled test.
- Record the location, timestamp, page and release version.
- Inspect DNS, TLS and HTTP behaviour.
- Examine browser errors and failed requests.
- Trace accepted submissions through backend integrations.
- Validate analytics separately and record the recovery.
If the failures started after a release, line up the deployment timeline against the first confirmed errors. That correlation is a useful lead, but it isn't proof of cause. Preserve logs before you roll back or touch multiple dependencies, or you'll lose the evidence you need to explain what happened.
Set alerts around the customer's outcome
Alert on conditions that affect users, and attach a documented response to each one. A brief transient error and a sustained inability to request a demo deserve different escalation paths. Paging someone at night for a two-second blip wears out the on-call rota quickly.
Google's service level objectives guidance offers a framework for choosing indicators and targets. For this journey, one indicator could be successful valid submissions divided by valid submission attempts. That measures what the business cares about rather than whether a server responded.
Set thresholds from business impact and observed behaviour, not from a number someone read elsewhere. Define the observation window, exclude test traffic explicitly and decide how retries are counted. Any proposed threshold should be treated as an internal target you can revisit, not a standard you've been promised.
The practical takeaway is simple: map the demo journey, give each failure point a clear owner, and test the complete path before the next campaign or website release. The team that can answer "can a prospect book a demo right now?" in minutes is the one that won't be surprised by a quiet week in the pipeline.


